


Human-in-the-loop is a way to build machine learning models with people involved at the right moments. In human-in-the-loop machine learning, experts label data, review edge cases, and give feedback on outputs. Their input shapes goals, sets quality bars, and teaches models how to handle grey areas. The result is Human-AI collaboration that keeps systems useful and safe for real use. Many teams treat HITL as last-minute hand fix. That view misses the point.
HITL works best as planned oversight inside the workflow. People guide data collection, annotation rules, model training checks, evaluation, deployment gates, and live monitoring. Automation handles the routine. Humans step in where context, ethics, and judgment matter. This balance turns human feedback in ML training into steady improvements, not one-off patches.
Here is what this article covers next.
We define HITL in clear terms and map where it fits in the ML pipeline. We outline how to design a practical HITL system and why it lifts AI training data quality. We pair HITL with intelligent annotation, show how to scale without losing accuracy, and flag common pitfalls. We close with what HITL means as AI systems grow more autonomous.
What is Human-in-the-Loop (HITL)?
Human-in-the-Loop (HITL) is a model development approach where human expertise guides, validates, and improves AI/ML systems for higher accuracy and reliability. Instead of leaving data processing, training, and decision-making entirely to algorithms, HITL integrates human expertise to improve accuracy, reliability, and safety.
In practice, HITL can involve:
- Data labeling and annotation: Humans provide ground truth data that trains AI models.
- Reviewing edge cases: Experts validate or correct outputs where the model is uncertain.
- Continuous feedback: Human corrections refine the system over time, improving adaptability.
This collaboration ensures that AI systems remain transparent, fair, and aligned with real-world needs, especially in complex or sensitive domains like healthcare, finance, or real estate. Essentially, HITL combines the efficiency of automation with human judgment to build smarter, safer, and more trustworthy AI solutions.
What is Human-in-the-Loop Machine Learning
Human-in-the-loop machine learning is an ML workflow that keeps people involved at key steps. It is more than manual fixes. Think planned human oversight in data work, model checks, and live operations.
Automation has grown fast. We moved from rule-based scripts to statistical methods, then to deep learning and today’s generative models. Systems now learn patterns at scale. Even so, models still miss rare cases and shift with new data. Labels age. Context changes by region, season, or policy. That is why edge cases, data drift, and domain quirks keep showing up.
The cost of mistakes is real. Facial recognition can show bias on skin tone and gender. Vision models in autonomous vehicles can misclassify a truck side as open space. In healthcare, a triage score can skew against a subgroup if training data lacked proper coverage. These errors erode trust.
HITL helps close that gap.
A simple human-in-the-loop architecture adds people to model training and review so decisions stay grounded in context.
- Experts write labeling rules, pull hard examples, and settle disputes.
- They set thresholds, review risky outputs, and document rare cases so the model learns.
- After launch, reviewers audit alerts, fix labels, and feed those changes into the next training cycle.
The model takes routine work. People handle judgment, risk, and ethics. This steady loop improves accuracy, reduces bias, and keeps systems aligned with real use.
Why HITL is essential for high-quality training data
Human-in-the-Loop (HITL) is essential for high-quality training data and effective data preparation for machine learning because AI models are only as good as the data they learn from. Without human expertise, training datasets risk being inaccurate, incomplete, or biased. Automated labeling hits a ceiling when data is noisy or ambiguous. Accuracy plateaus and mistakes spread into training and evaluation.
Rechecks of popular benchmarks found label errors around 3 to 6 percent, enough to flip model rankings, and this is where trained annotators walk into the picture. HITL ensures:
- Domain expertise. Radiologists for medical imaging. Linguists for NLP. They set rules, spot edge cases, and fix subtle misreads that scripts miss.
- Clear escalation. Tiered review with adjudication prevents single-pass errors from becoming ground truth.
- Targeted effort. Active learning routes only uncertain items to people, which raises signal without bloating cost.
Quality box: GIGO in ML
- Better labels lead to better models.
- Human feedback in ML training breaks error propagation and keeps datasets aligned with real-world meaning.
Here’s evidence that it works:
- Re-labeled ImageNet. When researchers replaced single labels with human-verified sets, reported gains shrank and some model rankings changed. Cleaner labels produced a more faithful test of real performance.
- Benchmark audits. Systematic reviews show that small fractions of mislabelled examples can distort both evaluation and deployment choices, reinforcing the need for human in the loop on high-impact data.
Human-in-the-loop machine learning offers planned oversight that upgrades training data quality, reduces bias, and stabilizes model behavior where it counts.
Challenges and considerations in implementing HITL

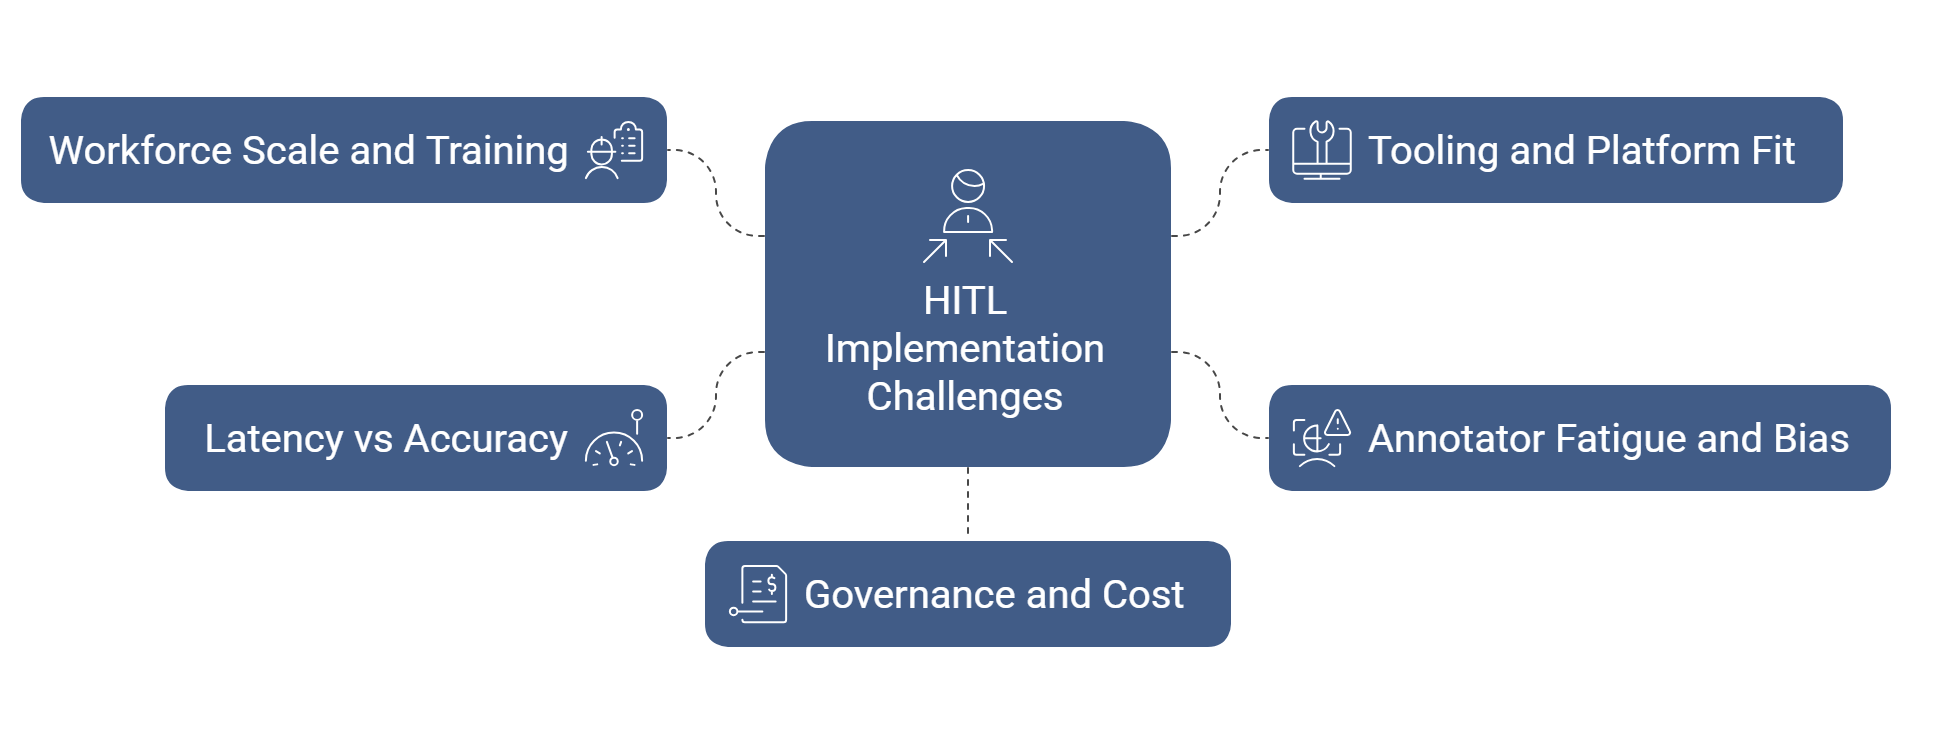
Implementing Human-in-the-Loop (HITL) comes with challenges such as scaling human involvement, ensuring consistent data labeling, managing costs, and integrating feedback efficiently. Organizations must balance automation with human oversight, address potential biases, and maintain data privacy, all while designing workflows that keep the ML pipeline both accurate and efficient.
- Workforce scale and training:
You need enough trained annotators at the right time. Create clear guides, short training videos, and quick quizzes. Track agreement rates and give fast feedback so quality improves week by week. - Tooling and platform fit:
Check that your labeling tool speaks your stack. Support for versioned schemas, audit trails, RBAC, and APIs keeps data moving. If you build custom tools, budget for ops, uptime, and user support. - Annotator fatigue and bias:
Long queues and repetitive items lower accuracy. Rotate tasks, cap session length, and mix easy with hard examples. Use blind review and conflict resolution to reduce personal bias and groupthink. - Latency vs accuracy in real time:
Some use cases need instant results. Others can wait for review. Triage by risk. Route only high-risk or low-confidence items to humans. Cache decisions and reuse them to cut delay. - Governance and cost:
Human-in-the-loop machine learning needs clear ownership. Define acceptance criteria, escalation paths, and budget alerts. Measure label quality, throughput, and unit cost so leaders can trade speed for accuracy with eyes open.
How to design an effective human-in-the-loop system
Start with decisions, not tools.
List the points where judgment shapes outcomes. Write the rules for those moments, agree on quality targets, and fit human-in-the-loop machine learning into that path. Keep the loop simple to run and easy to measure.
Use the right kinds of data labeling
Use expert-only labeling for risky or rare classes. Add model-assist where the system pre-fills labels and people confirm or edit. For hard items, collect two or three opinions and let a senior reviewer decide. Bring in light programmatic rules for obvious cases, but keep people in charge of edge cases.
Installing HITL in your company
- Pick one high-value use case and run a short pilot.
- Write guidelines with clear examples and counter-examples.
- Set acceptance checks, escalation steps, and a service level for turnaround.
- Wire active learning so low-confidence items reach reviewers first.
- Track agreement, latency, unit cost, and error themes.
- When the loop holds steady, expand to the next dataset using the same HITL architecture in AI.
Is a human in the loop system scalable?
Yes, if you route by confidence and risk. Here’s how you can make the system scalable:
- Auto-accept clear cases.
- Send medium cases to trained reviewers.
- Escalate only the few that are high impact or unclear.
- Use label templates, ontology checks, and periodic audits to keep consistency as volume grows.
Better uncertainty scores will target reviews more precisely. Model-assist will speed video and 3D labeling. Synthetic data will help cover rare events, but people will still screen it. RLHF will extend beyond text to policy-heavy outputs in other domains.
For ethical and fairness checks, start writing bias-aware rules. Sample by subgroup and review those slices on a schedule. Use diverse annotator pools and occasional blind reviews. Keep audit trails, privacy controls, and consent records tight.
These steps keep human-AI collaboration safe, traceable, and fit for real use.
Looking ahead: HITL in a future of autonomous AI
Models are getting better at self-checks and self-corrections. They will still need guardrails. High-stakes calls, long-tail patterns, and shifting policies call for human judgment.
Human input will change shape. More prompt design and policy setting up front. More feedback curation and dataset governance. Ethical review as a scheduled practice, not an afterthought. In reinforcement learning with human feedback, reviewers will focus on disputed cases and safety boundaries while tools handle routine ratings.
HITL is not a fallback. It is a strategic partner in ML operations: it sets standards, tunes thresholds, and audits outcomes so systems stay aligned with real use.
Deeper integrations with labeling and MLOps tools, richer analytics for slice-level quality, and a specialized workforce by domain and task type. The aim is simple: keep automation fast, keep oversight sharp, and keep models useful as the world changes.
Conclusion
Human in the loop is the base of trustworthy AI as it keeps judgment in the workflow where it matters. It turns raw data into reliable signals. With planned reviews, clear rules, and active learning, models learn faster and fail safer.
Quality holds as you scale because people handle edge cases, bias checks, and policy shifts while automation does the routine. That is how data becomes intelligence with both scale and quality.
If you are choosing a partner, pick one that embeds HITL across data collection, annotation, QA, and monitoring. Ask for measurable targets, slice-level dashboards, and real escalation paths. That is our model at HitechDigital. We build and run HITL loops end to end so your systems stay accurate, accountable, and ready for real use.