


Today any enterprise can take a page from big-data-rich companies like Linkedin, Netflix and Spotify and create an architecture to support real-time data analytics or monetization of Internet of Things (IoT) data. What is needed is a fast, reliable platform that can support IoT feeds and enable functionality like real-time financial metrics, real-time geolocation of inventory/goods or credit card fraud detection. Apache Kafka is that platform right now: an open source, distributed messaging system that is a key component in the Hadoop technology stack for deriving value from real-time data streams.
A Quick Primer on Kafka
Kafka is a distributed, scalable and reliable messaging system that provides seamless integration between applications/data streams using a publish-subscribe model. Kafka maintains feeds of messages in categories called topics. Producers (such as shopping cart events from website) publish messages to a Kafka topic and consumers (such as digital advertising system) read from topics. Since Kafka is a distributed system, topics are partitioned and replicated across multiple nodes called brokers.
Messages are simply byte arrays and generally are in String, JSON or Avro format. Each topic partition is managed with a log and each message in a partition is assigned a unique offset. Kafka retains all messages for a set time and consumers are responsible for tracking their location in each log and pulling them at a frequency they desire. This allows Kafka to support a large number of consumers with little overhead.
Kafka allows consumers to be part of a logical subscriber called a Consumer Group for scalability and tolerance. Each consumer inside a Consumer Group can subscribe to a specific partition of a topic to improve processing performance; as shown in the architecture diagram below.
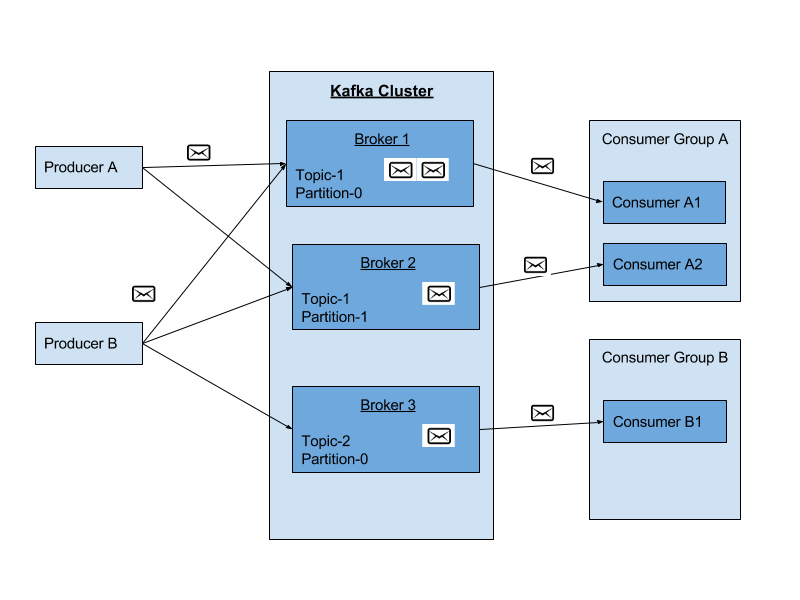

Kafkas unique design makes it faster, easier to scale and more reliable than traditional message brokers.
- Kafka is designed as a distributed system that is easily scalable. It has support for persistent messaging with O(1) disk structures that provide consistent time performance, even with terabytes of stored messages.
- It offers high throughput for both publishing and subscribing, supporting hundreds of thousands of messages per second, even with modest hardware.
- It supports multi-subscribers and automatically balances the Consumer Groups during failure.
- It persists messages on disk and therefore can be used for batched consumption and support for parallel data load into Hadoop.
The Kafka and Hadoop Ecosystem
For a big data solution or data lake based on Hadoop, Kafka can be a part of the technology stack. Other components in the stack that complement Kafka typically include:
- Spark Streaming: Receives data from Kafka so that Spark can do real-time processing of the data.
- Apache Flume: Has a source and sink for Kafka so that one can stream data from Kafka to Hadoop and from any Flume source to Kafka.
- Storm: Kafka topics can be consumed by a Storm topology for further processing in Storm. Additionally a Storm topology can emit an enriched event to a Kafka topic.
Applying Kafka to Your Business
Enterprises cant afford to rest on their laurels, even when theyve found success doing big data analytics in batch mode. At Zaloni, we leverage Kafka to help businesses broker massive streams of data to enable near real-time analytics for various use cases. Kafkas flexibility in supporting different producers and consumers, and its integration with a wide range of components like Storm, Flume and Spark, ensure that it can function as a key element even as the technology architecture changes to support future business needs.
References:
https://kafka.apache.org/
https://www.cloudera.com/documentation/kafka/latest/topics/kafka_using.html
https://hortonworks.com/hadoop/kafka/
https://labs.spotify.com/2016/02/25/spotifys-event-delivery-the-road-to-the-cloud-part-i/